GKE becomes more elastic: Scale to zero, save costs, and keep workloads responsive
Google Kubernetes Engine 1.37 introduces native scale-to-zero for sporadic workloads, eliminating idle costs while maintaining responsiveness through capacity buffers and direct metric integration.
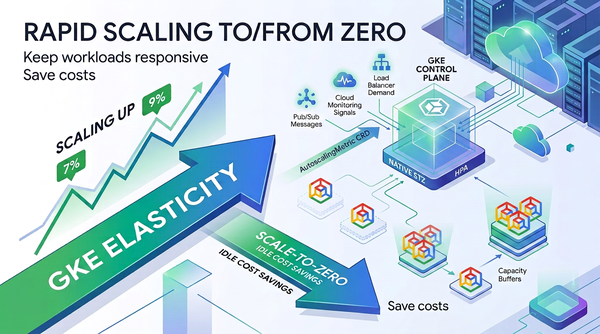
Google Kubernetes Engine (GKE) 1.37 introduces native scale-to-zero capabilities, allowing workloads such as batch processors or development environments to scale down completely to zero replicas when idle, thereby stopping resource consumption. This feature decouples infrastructure costs from workload readiness, addressing a long-standing challenge in cloud-native engineering. Previously, solutions like Kubernetes Event-Driven Autoscaling (KEDA) required complex management of custom resources and operators, adding overhead and latency.
The new approach integrates scale-to-zero directly into the GKE control plane, removing the need for external operators and reducing configuration complexity. It leverages HorizontalPodAutoscaler (HPA) with AutoscalingMetric, which now supports direct reading of external signals from Google Cloud Managed Service for Prometheus, Pub/Sub, Cloud Monitoring, or Load Balancer metrics. This unified path eliminates adapter dependencies and improves performance by reducing polling intervals and cold-start delays.
To implement scale-to-zero, users define a metric—such as undelivered Pub/Sub messages—and configure an HPA with a minimum replica count of zero. GKE’s capacity buffers further enhance responsiveness by maintaining warm compute resources that can be instantly claimed when scaling from zero. Active buffers serve hundreds of workloads simultaneously, while standby buffers refill active capacity as needed, ensuring both low latency and cost efficiency.
The cold-start challenge is mitigated by capacity buffers, which provide pooled warm capacity to eliminate the typical 60-90 second node provisioning delay. Active buffers act as wildcard capacity for multiple workloads, while standby buffers maintain readiness for sustained loads at a fraction of the cost. This combination ensures near-instant scaling without sacrificing performance or incurring idle expenses.